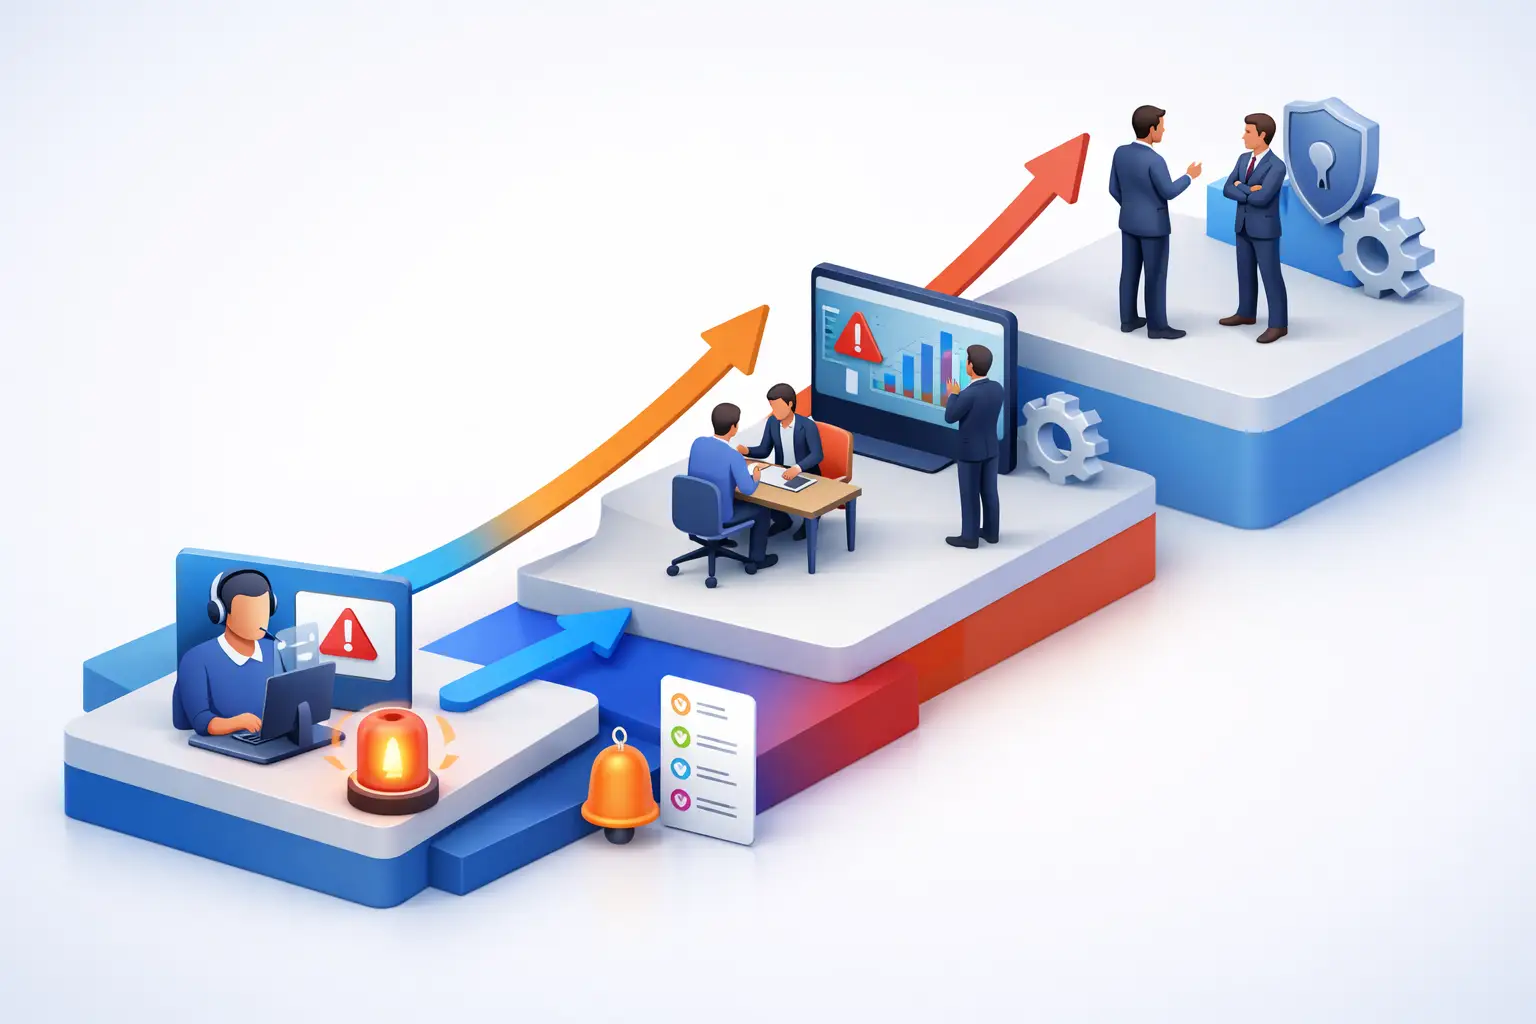
An incident rarely becomes critical because the first signal was missed. More often, it becomes critical because people were unsure when to raise it, who had authority to act, or how quickly a local issue had to become an executive concern. That is why understanding how to create escalation protocols matters. A well-structured protocol does not add bureaucracy. It removes hesitation at the point where delay becomes loss.
For organisations with complex operations, escalation is not simply a customer service mechanism or an IT support workflow. It is a control function. It protects continuity, limits regulatory exposure, supports accountable decision-making and gives leaders a reliable path from front-line detection to proportionate oversight. The challenge is that many protocols are either too vague to be useful or so rigid that teams work around them when pressure rises.
What effective escalation protocols are designed to do
An escalation protocol should answer four practical questions. What constitutes an issue that must be raised, when it must be raised, who must receive it and what authority transfers at each stage. If any one of those elements is unclear, escalation becomes inconsistent.
The strongest protocols are designed around decision velocity and control. They help operational teams recognise thresholds early, ensure managers are not bypassed or overloaded unnecessarily, and create a visible record of how the organisation responded. This is especially important in regulated and reputationally sensitive sectors, where the difference between a managed event and a reportable failure often depends on timing and governance discipline.
There is also a trade-off to manage. If thresholds are too low, senior teams are flooded with noise and begin to ignore alerts. If thresholds are too high, incidents remain local until options narrow. Effective design sits between those extremes.
How to create escalation protocols that work under pressure
The right starting point is not a template. It is a realistic view of the decisions your organisation must make when conditions deteriorate. Escalation should be built around those decisions rather than around departmental preferences.
Start with business impact, not reporting lines
Many organisations begin by mapping who reports to whom. That may reflect hierarchy, but it does not necessarily reflect risk. An escalation protocol should first identify the types of impact that matter to the business: safety, service availability, legal exposure, financial loss, data compromise, customer harm, contractual breach and reputational damage.
Once those impact categories are defined, establish what level of degradation or uncertainty requires escalation. A systems outage affecting one internal team is not the same as an outage affecting external customers across multiple markets. A supplier delay may remain operational, or it may quickly become a material continuity issue if inventory, patient care or regulated delivery obligations are involved.
This impact-led approach creates a stronger basis for escalation because it aligns the protocol with enterprise risk and continuity priorities rather than with personality or status.
Define clear triggers and thresholds
People escalate reliably when trigger points are specific. They hesitate when language is subjective. Terms such as significant issue, urgent concern or high priority create room for interpretation at exactly the wrong moment.
Better protocols define thresholds in operational terms. That might include service disruption exceeding a set duration, unauthorised access to sensitive data, expected financial loss above an agreed level, media interest, law enforcement contact, health and safety implications or failure of a critical third party. In some environments, a threshold may also be the absence of information. If a site cannot confirm staff safety after a major event, that uncertainty alone may justify escalation.
Good thresholds combine quantitative measures with qualitative judgement. You cannot reduce every scenario to a number, but you can give teams enough structure to avoid guesswork.
Separate operational escalation from governance escalation
One common weakness is treating escalation as a single ladder. In practice, there are usually at least two tracks. The first is operational and focuses on restoring service, containing harm and allocating resources. The second is governance-led and focuses on oversight, accountability, regulatory obligations and strategic decision-making.
These tracks often overlap, but they should not be confused. A technical team may need to escalate laterally to security, facilities or supply chain to stabilise operations. Separately, the issue may need to be escalated vertically to executive leadership, the board, a risk committee or legal counsel because of its implications.
When protocols fail to distinguish between these pathways, organisations either over-escalate routine incidents into executive forums or under-escalate serious matters that require formal oversight.
Assign authority at each escalation level
Escalation is not only about notification. It is about transfer or expansion of authority. If a protocol says an issue must be escalated to a senior manager, that manager must know what decisions they are expected to take and what powers they hold.
At each level, define who can approve expenditure, engage external advisers, activate continuity arrangements, pause operations, notify regulators, brief customers or convene a crisis management team. This should be explicit. During a live event, teams should not need to negotiate authority in parallel with response actions.
This is where escalation protocols connect directly to governance. Authority should reflect the organisation’s existing decision rights, delegated authorities and crisis management structure. If those elements are not aligned, escalation becomes performative - lots of notifications, limited control.
Build time expectations into the protocol
A protocol without time standards is incomplete. It is not enough to state that a matter must be escalated. The protocol should specify how quickly that must happen and how updates are maintained.
Some incidents require immediate verbal escalation followed by written confirmation. Others may allow staged assessment within a defined window. The timing should reflect consequence and pace. Cyber incidents, safety events and public allegations often demand faster executive visibility than contained technical faults.
Update expectations matter as well. Once escalated, teams need to know whether they are expected to report every 30 minutes, at key decision points, or only when the impact changes materially. Over-reporting consumes response capacity. Under-reporting leaves leadership exposed.
Make communication paths simple enough to use
Complex contact trees often look impressive on paper and fail in practice. An escalation protocol should make it easy for people to act correctly under stress, outside office hours and with incomplete information.
That means maintaining current contact information, primary and alternate roles, communication channels and fallback methods. It also means deciding in advance whether certain incidents require phone contact, secure messaging, incident management platforms or formal written briefings. In geographically distributed organisations, local time zones and regional leadership coverage need to be considered.
The protocol should also state what information must be included in an escalation. A short, standardised format usually works best: what happened, when it happened, current impact, actions taken, decisions required and next update time. Consistency improves speed and reduces distortion as information moves upwards.
Test the protocol against realistic scenarios
The real test of how to create escalation protocols is whether they function when conditions are unclear, facts are changing and the first assessment turns out to be wrong. Tabletop exercises are useful precisely because they expose where thresholds are ambiguous, authority is uncertain or communications are too slow.
Scenario testing should not focus only on major crises. Mid-level events often reveal more about protocol quality because they sit in the grey area where escalation decisions are least obvious. A supplier issue affecting one region, a suspicious payment request, a facilities failure during a high-profile event or a staff misconduct allegation involving a senior manager can all test whether the protocol guides judgement properly.
After each exercise or live incident, review what was escalated, what was delayed, who lacked clarity and whether thresholds need adjustment. Protocol design is iterative. Static documents age quickly.
Common mistakes that weaken escalation protocols
The most frequent problem is writing protocols from a compliance perspective only. Compliance matters, but if the protocol does not help people make fast operational decisions, it will be ignored when pressure rises.
A second problem is assuming managers will naturally know when to escalate. Experience helps, but reliance on individual judgement creates inconsistency across regions, business units and shifts. The protocol should reduce dependence on heroics.
A third weakness is failing to account for reputational and leadership issues. Some incidents may be operationally containable but still require rapid executive awareness because they involve public trust, regulatory sensitivity or board-level accountability.
Finally, many protocols are not maintained. Contact details change, business structures evolve, third-party dependencies increase and regulatory expectations shift. An escalation protocol should be reviewed as part of the wider resilience and governance cycle, not left as a static annex.
For organisations building mature resilience capabilities, escalation is one of the clearest indicators of operational discipline. It shows whether risk signals can travel quickly enough, whether authority is usable under pressure and whether governance remains connected to the realities of front-line disruption. That is where structured advisory support from specialists such as JABA can add practical value. The goal is not more process. The goal is earlier control.
A useful protocol gives people confidence to raise issues before they become irreversible, and gives leaders the visibility to act while options still exist.